Code-as-World Turns Real Videos into Physics Sims
Code-as-World converts real-world video into editable MuJoCo physics simulations, offering a new path for training AI in robotics, vehicles, and physical reasoning.
Written by AI. Yuki Okonkwo
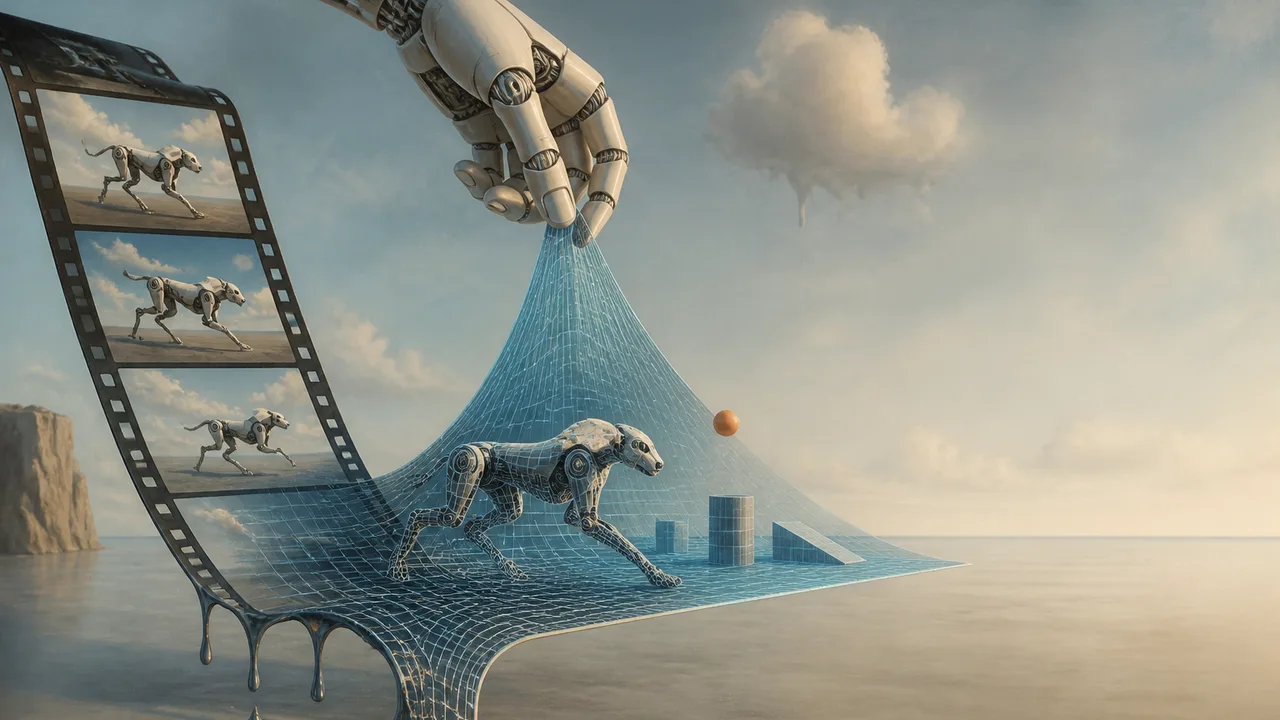
Imagine watching a video of someone setting a glass on a table and, instead of your brain quietly filing away "glass, table, gravity, done," a system reads that footage and produces a fully editable physics environment where you can poke the glass, change the table's friction coefficient, or swap in a steel ball and rerun the whole scene. That's the core promise of Code-as-World, and it lands at a moment when the AI field is actively wrestling with a thorny question: what does it actually mean for a model to understand the physical world?
The short answer most researchers have been living with is: we're not sure, but we'll know it when it predicts the next video frame correctly. Code-as-World is a bet that this answer is wrong, or at least incomplete.
What "Code-as-World" actually does
According to marktechpost.com, the approach extracts editable scene code directly from real-world videos and renders those scenes inside MuJoCo, the open-source physics engine that robotics researchers have been leaning on for years. The resulting simulation isn't a video lookalike. It's a living, manipulable environment where you can change parameters and run the physics forward from any state you choose.
That matters because of what it enables downstream. The extracted simulations can serve as training environments for AI systems learning physical reasoning tasks, giving them a world they can interact with rather than a sequence of images they can only observe.
MuJoCo (short for Multi-Joint dynamics with Contact, if you want the full name) has long been a workhorse in robotics research precisely because it handles the fiddly stuff that makes physical simulation hard: contact forces, joint constraints, material properties, and the way objects actually deform and interact at the boundary. Getting those details right from scratch is painstaking. Getting them from video, automatically, is a different kind of hard.
The frame-prediction trap
Here's where the architectural choice gets genuinely interesting. The dominant paradigm for AI "world models" over the past few years has been latent video prediction: you train a neural network to represent the current state of the world as a compressed internal vector (the "latent"), then train it to predict what that latent looks like one frame later. Scale that up far enough, the thinking goes, and you get something that implicitly understands physics because it has to, in order to keep predicting correctly.
The paper behind Code-as-World, summarized at arxiv.org, proposes a different frame entirely. Rather than learning a latent video transition model, the system constructs an executable physics world from user input. The research describes this as a shift "from frame prediction to simulator-aware world construction, where the system must specify geometry, bodies, joints, contacts, material" properties explicitly.
That's not a subtle distinction. In latent video prediction, the model's understanding of "friction" or "mass" exists somewhere inside billions of parameters, in a form no human can directly inspect or edit. In Code-as-World's approach, friction and mass are explicit fields in the generated scene file. You can read them. You can change them. You can ask: does the model's estimate of this object's weight actually match reality?
This explicitness is both the approach's strength and its most honest limitation. Explicit representations are auditable and editable, which is great for researchers who want to understand what the system learned and for engineers who want to tweak simulations quickly. But extracting those explicit parameters correctly from raw video is genuinely hard. Estimating mass from footage alone, without depth sensors or known reference objects, is an inverse problem that computer vision researchers have been picking at for decades without a clean solution. The sources available for this piece don't detail exactly how Code-as-World resolves that challenge, and that's worth noting plainly: the reported capabilities sound compelling, but the engineering specifics of how the system infers physical properties remain opaque based on what's been published so far.
Why robotics and autonomous systems care
The practical stakes here are real. As techaimag.com notes, Code-as-World's ability to generate accurate physical simulations from video also positions the approach as a training data pipeline, not just a visualization tool.
This is the piece that makes robotics researchers sit up. One of the stubborn problems in physical AI is the sim-to-real gap: you train a robot arm in simulation, it gets really good at grasping things in that clean, perfectly-modeled world, and then you drop it into a real kitchen and it confidently knocks the coffee mug off the counter. 🤦 The gap exists because simulations, however good, are built on assumptions that don't match the messiness of physical reality.
If you can build simulations from real-world video footage, you're closing that loop differently. The simulation's starting point isn't a hand-crafted idealization; it's an observed scene, with all the imperfections that implies. Whether that actually narrows the sim-to-real gap in practice is an empirical question the field will need to answer with controlled benchmarks, and those benchmarks aren't part of the public record yet on this particular system.
For autonomous vehicles, the implications are similarly layered. The ability to take dashcam or sensor footage from an edge case (a cyclist doing something unexpected, a pothole that swallows a tire) and generate a physics-accurate simulation of that scenario could dramatically improve how corner cases are incorporated into training pipelines. Right now, collecting and hand-annotating those scenarios is expensive and slow. An automated pipeline from video to runnable simulation would change that math considerably.
What this isn't, yet
It's worth being careful about scope here. The sources don't describe a system that handles arbitrary, wild, chaotic video and magically produces a perfect simulation every time. The approach appears most naturally suited to scenes with identifiable objects and interpretable geometry, the kind of structured environment where a coding agent can meaningfully specify "body A, connected to body B via a hinge joint with these angular limits." Highly cluttered, unstructured, or fast-moving scenes present harder inference problems.
There's also the question of what "editable" means in practice. An editable simulation is only as useful as the interface that lets you do the editing. If researchers need to hand-tune generated MuJoCo XML files to get usable results, the pipeline is valuable but still laborious. If the extraction is accurate enough to use with minimal correction, it's transformative. The honest answer, based on what's available, is: we don't know yet where Code-as-World sits on that spectrum for real-world use cases.
The deeper question this raises
There's a philosophical undercurrent here that I find more interesting than the benchmark questions. The latent video prediction camp and the explicit physics construction camp represent genuinely different theories of what "understanding" the physical world should look like in an AI system.
One says: learn a representation rich enough to predict observations, and understanding is implicit in that capability. The other says: understanding means being able to specify the world in terms that reflect how it actually works, with geometry, mass, joints, contacts, and constraints that you can inspect and reason about.
Neither position is obviously wrong. Humans, after all, develop intuitive physical understanding long before anyone explains to us what a center of mass is. But humans can also learn physics formally and use that formal knowledge to solve problems our intuition gets wrong. The question Code-as-World implicitly raises is whether AI systems need both modes, and whether explicit, executable representations might be the missing ingredient for the physical reasoning tasks where current models still struggle.
That's not a question with a clean answer today. But it's a better question than "did the frame prediction loss go down?" And better questions tend to point toward more interesting places.
More Like This
Harness Engineering: The New Frontier in AI Development
AI companies are shifting focus from better models to better infrastructure. Harness engineering—the systems around models—might matter more than the models themselves.
NVIDIA Lyra 2.0 Builds 3D Worlds From One Photo
NVIDIA's Lyra 2.0 generates persistent 3D worlds from a single image. Here's the technical trick that finally keeps them from breaking down.
OpenAI Shut Down Sora to Build Robot Brains Instead
OpenAI killed its consumer video app Sora to focus on world simulation for robotics. What does this pivot mean for AI's future?
OpenAI's Codex Desktop App Launches With Curious Bugs
OpenAI's new Codex desktop app brings AI coding to macOS with a GUI, but early testing reveals surprising UI quirks and context issues.
MolmoMotion Links Language to 3D Motion Forecasting
Allen Institute for AI's MolmoMotion forecasts 3D point trajectories from language instructions—a shift that could reshape robotics, AR, and simulation.
Robotics in 2026: Real Progress, Real Limits
Top AI and robotics researchers gathered at YC to map what's actually been solved—and what hasn't. Here's an honest account of where the field stands in 2026.
How Optimization Powers Modern AI and Engineering
From training ChatGPT to imaging black holes, optimization is the hidden engine behind modern AI and engineering. Steve Brunton's lecture explains how.
David Patterson on CPUs, GPUs, TPUs, and 50 Years in Computing
Turing Award winner David Patterson breaks down RISC vs. CISC, the GPU-to-TPU shift, Moore's Law's real status, and what 50 years in computing actually taught him.