MolmoMotion Links Language to 3D Motion Forecasting
Allen Institute for AI's MolmoMotion forecasts 3D point trajectories from language instructions—a shift that could reshape robotics, AR, and simulation.
Written by AI. Marcus Chen-Ramirez
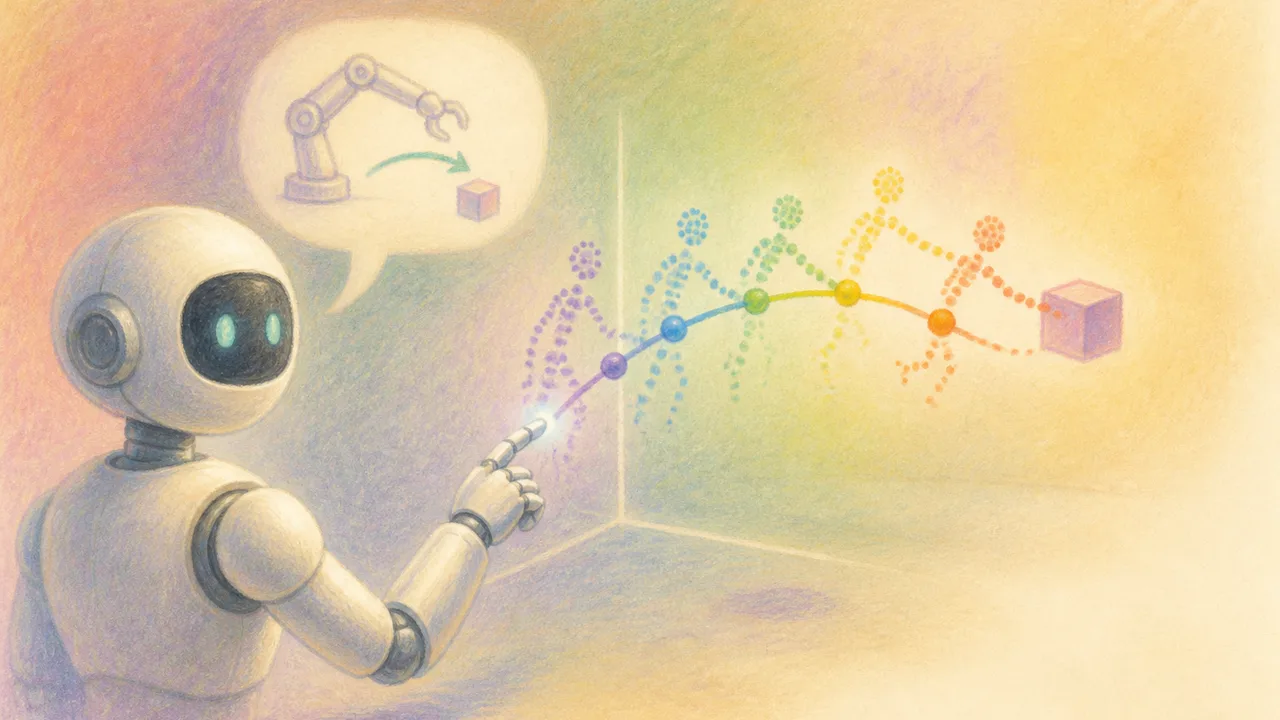
There's a particular gap in how AI has understood the physical world that's worth naming precisely before we talk about what just changed. Most vision-language models—even the impressive ones—are essentially very sophisticated image captioners. They can tell you what's in a scene. Some can point at things. Almost none can reliably tell you what those things are about to do in three-dimensional space, and even fewer can do so in response to a plain-language instruction.
MolmoMotion, introduced by researchers at the Allen Institute for AI (Ai2), is a serious attempt to close that gap.
What MolmoMotion Actually Does
The setup is more specific than the name implies, so it's worth being precise. According to the MolmoMotion project page, the system takes three inputs: a short video history of a scene, a set of query points on an object within that scene, and a language instruction describing an action. From those inputs, it predicts the future 3D trajectory of each query point—where those points will travel through space as the described action unfolds.
What makes this harder than it sounds is that "motion" in the real world is not a single phenomenon. The project page notes that MolmoMotion handles rigid motion (a box sliding across a table), articulated motion (a robotic arm bending at a joint), and deformable motion (a piece of cloth crumpling). It handles these across indoor, egocentric, and outdoor scenes. That's a meaningfully broad scope, not a demo cherry-picked from a narrow domain.
The model's backbone is Molmo 2, Ai2's open vision-language model with video understanding and grounding capabilities. As both the Ai2 blog and Hugging Face post explain, Molmo 2 is what lets MolmoMotion connect the language instruction to specific objects and spatial points in an image. The language isn't decoration—it's the mechanism by which the model is steered toward a particular future rather than forced to predict the single most statistically likely motion.
This matters more than it might initially appear. A robot that can only predict what an object will probably do is useful. A robot that can predict what an object will do if you push it left versus right, or open it versus close it is categorically more useful. Language instruction is the lever that makes conditional prediction possible at scale.
The Infrastructure Behind the Claim
Research papers making capability claims live or die by their infrastructure. Benchmark games are easy to win if you also designed the benchmark. So the methodological scaffolding here deserves scrutiny.
The Ai2 team built what they describe as a "full stack" for studying this problem. According to the arXiv paper, that stack has two major components: MolmoMotion-1M, a training corpus of action-described, object-grounded 3D point trajectories annotated from 1.16 million unconstrained videos; and PointMotionBench, a human-verified evaluation benchmark spanning 111 object categories.
The scale of the training corpus—over a million videos, unconstrained—matters because it's a hedge against the overfitting that plagues smaller, curated datasets. The 1.16 million figure suggests the team wasn't just collecting clean lab footage. Unconstrained video is messy, which is both harder to learn from and more representative of the actual world a deployed system would encounter.
PointMotionBench spanning 111 object categories is similarly notable. A benchmark that covers enough categories to be genuinely challenging, and that's human-verified rather than algorithmically generated, is one of the more credible signals that the researchers are trying to measure something real. Whether it will survive external scrutiny—whether the research community will find blind spots in the benchmark design—is a question that only time and peer engagement can answer.
On the generative side, according to the full paper on arXiv, MolmoMotion uses flow-matching-based trajectory generation. Flow matching is a relatively recent technique in generative modeling—it produces smoother, more stable training dynamics than earlier approaches and has been gaining traction in continuous-output settings, which is exactly what trajectory prediction requires. Using it here is a reasonable architectural choice, not a gimmick.
Where This Fits in the Broader Picture
It's useful to situate MolmoMotion against related work. The alphaXiv overview references a system called ObjectForesight, which also targets future 3D object trajectory prediction from human videos. The fact that multiple groups are converging on this problem space is itself a signal—it suggests the field has identified a genuine capability gap and is racing to fill it.
What distinguishes MolmoMotion from that prior work, at least according to Ai2's framing, is the language conditioning. Most trajectory prediction systems are reactive: they predict motion based on physics, object properties, and context. Language-conditioned prediction is generative in a different sense—it allows a user or an upstream system to specify intent, which shifts the model from "what will happen" to "what will happen if I do X."
That shift has direct consequences for the applications most commonly cited in connection with this work: robotics, simulation, and augmented reality.
In robotics, the value is fairly obvious. A manipulation system that can forecast where a grasped object's surface points will travel—under a specific action described in language—has a more reliable internal model for planning and error correction. The question is whether MolmoMotion's predictions are accurate enough and fast enough to be useful in real-time control loops, which the published work doesn't fully address yet. Benchmark performance and deployment performance are not the same thing.
In simulation and augmented reality, the use case is somewhat different. Here the value is less about real-time control and more about generating plausible, language-steerable motion for synthetic environments. If you're building a training dataset for another robot or an AR experience where virtual objects need to interact convincingly with real ones, a system that can generate diverse 3D trajectories on instruction is genuinely useful infrastructure.
What Remains Open
Ai2 is a nonprofit research organization—it's not a product company with a deployment pipeline. That's worth holding in mind when reading capability claims. The incentive structure is different from a lab embedded in a commercial organization: there's less pressure to overstate near-term deployment, and more latitude to publish work that's honest about its own limitations.
That said, the gap between a research demonstration and integrated deployment is one the field has consistently underestimated. MolmoMotion's pipeline—video history plus query points plus language instruction—assumes a fairly clean setup. In a real robotics deployment, you need accurate depth estimation to get those initial 3D positions, reliable object tracking to maintain query point identity across frames, and all of this has to run within the latency budget of a control system. None of those problems are unsolved, but they're not free either.
The OpenCV community's coverage of MolmoMotion is a good indicator that the work is landing in practitioner communities, not just academic ones. OpenCV's audience is engineers who build things. When they pay attention, it's usually because something has cleared a minimum bar of practical relevance.
Meanwhile, the broader context for where language models are heading—including on constrained hardware—is evolving quickly. KDnuggets' recent piece on small language models makes the point that SLMs are increasingly viable for specialized, on-device tasks. MolmoMotion currently runs on the Molmo 2 backbone, which is not a small model. Whether the language-conditioning architecture could be distilled or adapted for edge deployment in robotics hardware is an open question worth watching.
What's genuinely novel about the MolmoMotion framing is the argument embedded in it: that language is not just a useful interface for querying AI systems about the world, but a control signal for steering prediction about the world's future states. That's a different claim than "language models are good at describing things." If it holds up under external scrutiny and real-world testing, it suggests language-conditioned spatial reasoning is a more general tool than the current generation of vision-language models implies.
The question isn't whether MolmoMotion is impressive research. The more interesting question is whether the language-conditioning approach scales to the messiness of actual deployment—and whether the field learns something durable from trying.
More Like This
Gemma 4's Architecture Rethinks Multimodal AI
Google DeepMind's Gemma 4 ditches separate vision encoders for a unified architecture. Here's what that design choice actually means for open-source AI.
Ernie 5.0: Baidu's Bold AI Leap Forward
Explore Baidu's Ernie 5.0, a new AI model challenging GPT-4 with its multimodal capabilities and cost-effectiveness.
NVIDIA Lyra 2.0 Builds 3D Worlds From One Photo
NVIDIA's Lyra 2.0 generates persistent 3D worlds from a single image. Here's the technical trick that finally keeps them from breaking down.
AlphaGo From Scratch: What Go Teaches Modern AI
Eric Jang rebuilt AlphaGo with modern tools—and what he found reveals a fundamental tension at the heart of how we're training today's LLMs.
OpenAI's Codex Is Growing Up Fast—And Getting Weird
OpenAI's latest Codex updates add browser control, AI-reviewed approvals, and... animated pets? A look at where AI coding tools are actually heading.
Google Gemini 3.7 Flash: Coding Power at Low Cost
Google's Gemini 3.7 Flash arrives with serious coding benchmarks, a 1M-token context window, and pricing designed to scale. Here's what it actually means.
Google Gemini Omni Flash Opens API Access
Google's Gemini Omni Flash is now available via API, bringing conversational video editing and multimodal inputs to developers. Here's what it can and can't do.
Gemini Nano Gets Faster on Pixel Without Retraining
Google's frozen Multi-Token Prediction retrofits speed gains onto existing Gemini Nano models—no retraining needed. Here's what that means for on-device AI.