NVKE Aims to Make Kubernetes GPU Clusters Easier to Run
NVKE targets the headaches of running GPU workloads on Kubernetes. Here's what teams should check before adding another layer to costly AI infrastructure.
Written by AI. Tyler Nakamura
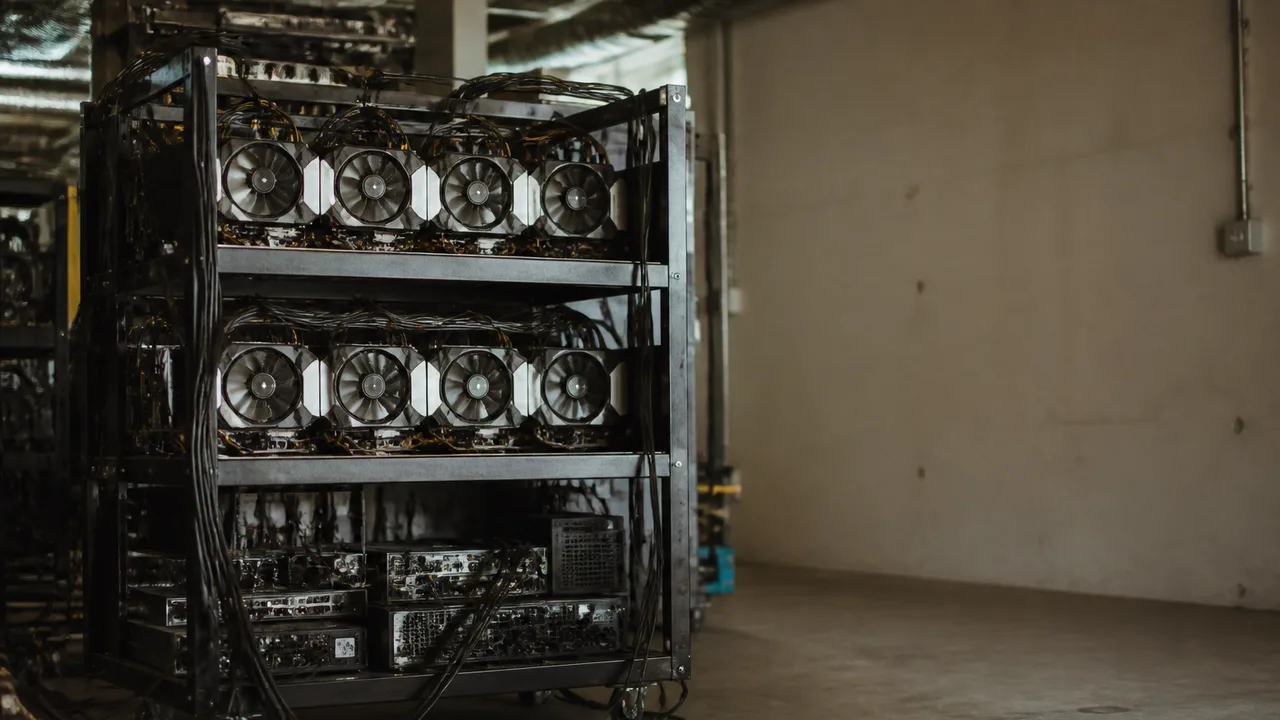
The Nvidia Kubernetes Engine (NVKE) repository points at a problem many AI teams eventually meet: getting expensive GPUs into the hands of the right jobs without turning cluster administration into a second full-time project. Kubernetes can coordinate containerized applications, but a GPU is a scarce, costly resource. A training run waiting in a queue and an inference service waiting for capacity can put very different demands on the same machines.
NVKE is an open-source effort aimed at organizing Kubernetes deployments around GPU-heavy work. It is an Nvidia release, while its GitHub repository sits under the dsx-ai-factory account; the name and project listing alone cannot confirm Nvidia's role, production readiness or supported configurations. Anyone considering it should establish those details before treating the branding as a support promise.
The appeal is easy to understand. If you already own or rent GPUs, idle time hurts. So does a setup that requires an operator to piece together deployment steps every time a team starts a new workload. A tool that simplifies those steps could save attention and make capacity easier to share. The buying decision, though, is about the work it removes after installation, including the work of maintaining the tool itself.
Why GPUs Complicate an Ordinary Kubernetes Cluster
Kubernetes gives teams a common way to deploy applications and decide where they run. GPU workloads make that decision awkward. An ordinary web service might scale by adding more copies across general-purpose machines. A job that needs an accelerator has fewer places to go, and those places may already be occupied. Some jobs need a short burst; others run long enough to block capacity that another team expected to use.
Allocation is only the first headache. Operators also have to think about the software that lets a container use the hardware, how workloads request resources, what happens when jobs queue and how they can see whether capacity is busy or sitting idle. Each question has a practical consequence. A deployment process that gets a model running but leaves operators guessing about utilization can still produce a nasty infrastructure bill.
Then come the competing priorities. An inference service serving users may need predictable access to hardware. A training job may be able to wait, but could use a large block of capacity once it starts. Give everything the same priority and somebody ends up waiting at the wrong time. Create elaborate rules for every case and the cluster becomes harder to operate. That is the niche NVKE is addressing: the gap between having Kubernetes and making a GPU cluster usable across jobs and teams.
The Job a New Layer Would Have to Do
A good GPU orchestration tool would make common tasks repeatable while letting operators see the decisions underneath. If a team can define a workload once, deploy it consistently and understand why it landed on a given machine, that cuts down on manual coordination. If the tool also helps teams see which accelerators are committed and which are free, it becomes easier to plan work without buying capacity simply because existing capacity is hard to find.
Those are useful tests for NVKE, rather than features to assume from its name. A prospective user should ask what the project installs, what it configures, which parts of Kubernetes it relies on and what it changes. Does it manage an existing cluster or expect to shape a new one? How does it handle updates and failures? Can an operator inspect and override scheduling choices? A setup wizard is lovely until the first job gets stuck and nobody can tell which setting made the call.
There is also a difference between reducing setup work and improving GPU use. Faster deployment could help teams get projects running. Better allocation would require teams to examine what happens when multiple jobs compete, whether priorities behave as expected and whether hardware sits idle despite demand. Both outcomes have value, but they call for different tests. A short demonstration of a successful deployment cannot answer every question an operator faces on a busy Tuesday.
Open source gives teams a chance to examine code and adapt it. It also puts maintenance questions on the table. Who reviews changes? How quickly do fixes arrive? What happens when an underlying component changes? Each additional layer can simplify the user-facing workflow while adding another set of permissions, configuration files and upgrade steps for the people keeping the cluster alive.
Compare It with the Setup You Already Have
NVKE's most realistic competitor for many organizations is their existing Kubernetes workflow. A team with a small number of predictable GPU jobs might find that its current deployment templates and operating procedures cover the basics. Adding a new project to save a few setup steps would then create an extra upgrade and security task. A team juggling many users and workloads has a stronger reason to investigate whether a dedicated layer reduces repeated coordination.
Managed infrastructure offers another path. It can shift some cluster setup and upkeep to a provider, although teams still need to understand what they pay for and how much control they keep. At the budget end, the sensible move may be to use a smaller pool of GPUs more deliberately, schedule flexible work when capacity is free or avoid building a complex cluster until demand justifies one. The cheapest orchestration problem is the one you do not create early.
Those comparisons need to include people, not just hardware. A project that saves GPU time but consumes hours of operator attention might be the wrong fit for a small team. A managed option that is simpler day to day may come with less flexibility. An in-house setup can offer control, provided someone has time to maintain it. None of these choices wins on its name or a feature checklist; the workload mix and the team's capacity to support the system decide the fit.
What to Check Before a Pilot
Start with the project's documentation and supported configurations. Check the Kubernetes versions, hardware and software components relevant to your own environment. Review release activity and issue handling, then map out how the project would interact with your current drivers, deployment process, monitoring and access controls. If those answers require assumptions, resolve them before moving beyond a test cluster.
For the pilot, choose jobs that resemble your actual work. Run one that needs quick access to a GPU and another that can wait. Introduce contention, restart a failed job and watch what operators can see and change. Record the setup steps NVKE replaces, along with the new steps it introduces. The comparison should include time to deploy, time to diagnose a problem and the visibility needed to avoid leaving costly hardware unused.
Finally, plan the exit before committing the cluster. Teams should know which configurations they can keep, which depend on NVKE and how they would roll back an upgrade that disrupts jobs. That is ordinary caution for any layer touching production workloads, with extra weight when every hour of confused GPU scheduling has a cost.
NVKE is aimed at a clear operational headache. Its opportunity is to make scarce accelerators easier to share without taking away the controls operators need when the queue fills up. The most persuasive demonstration would be a team deploying its own jobs, handling a failure and finding that both the GPUs and the humans spend less time waiting.
More Like This
Antigravity A1 Drone Review: 360 Camera Meets FPV
The Antigravity A1 merges a 360-degree camera with FPV drone flight. Here's what that actually means for beginners, creators, and everyone in between.
The Real Talk Guide to Your First 100 YouTube Subscribers
VidIQ breaks down what actually works for new creators in 2026. Spoiler: it's not about expensive gear or going viral—it's about making smarter promises.
Nscale IPO Tests the Economics of the Neocloud Boom
Nscale's IPO filing pairs 1,252% revenue growth with a $1.02 billion loss. CoreWeave shows why demand, debt and dilution matter for investors.
Eminent Domain Is Being Used to Build Data Centers
Power companies in Georgia and Pennsylvania are using eminent domain to seize private land for AI data center infrastructure. Here's what that actually means.
Google Cloud's Chip Strategy Explained by CEO Thomas Kurian
Google Cloud CEO reveals why owning TPU chips gives them a compute advantage over competitors relying on Nvidia—and why they're still hiring despite AI automation.
Crack the Code: AI-Ready Infrastructure Essentials
Explore how to build AI-ready infrastructure with data pipelines, MLOps, and smart compute choices.
UNAM's AI Exam Proctoring Failure Forces 58,000 Retakes
Nearly 160,000 students took UNAM's AI-proctored entrance exam remotely. Now 58,000 must retake it in person. Here's what actually went wrong.
Major Labels Want AI Music Off the Charts
Universal, Sony, and Warner are pushing to ban AI-generated songs from global charts. Here's what their proposal actually says — and who it really helps.