Voxel51 3.0 Unifies Data Work for Physical AI Teams
Voxel51 3.0 unifies sensor-data search, annotation and evaluation for physical AI. Its test: reproducible datasets, hardware compatibility and agent access controls.
Written by AI. Marcus Chen-Ramirez
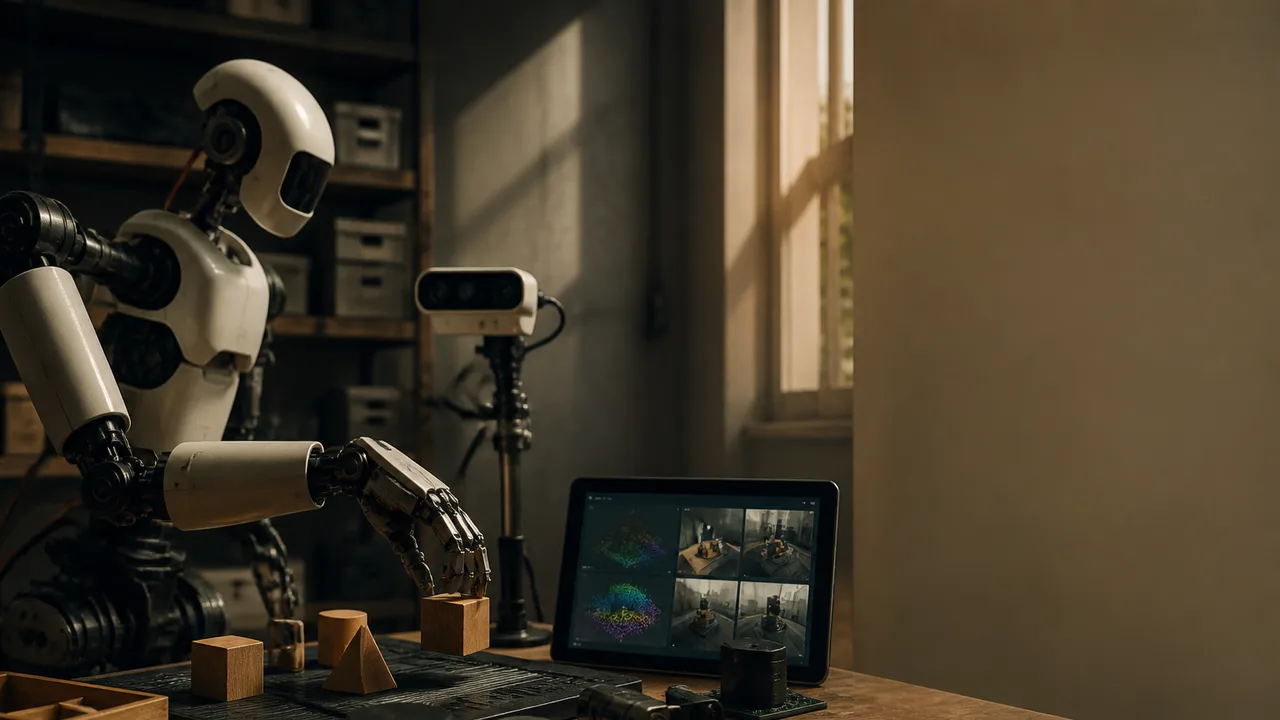
Voxel51 introduced a unified data platform for physical AI on October 15, 2026. Version 3.0 brings search, curation, annotation and evaluation into one system for teams working with video and other sensor records. The pitch concerns a stubborn interval in AI development: the time between collecting a recording and deciding whether it is useful for training or testing a model.
A robot can produce hours of footage while performing a task. A development team might need only the moments when it misjudged an object, lost track of its position or encountered an unfamiliar setting. Someone has to find those moments, label them, decide where they belong in a dataset and check whether a later model handles them better. Each transfer between tools creates another opportunity to lose context. Voxel51 wants those decisions to happen in one workflow.
That is a more concrete proposition than the phrase “physical AI” usually gets. The term can encompass robots and other systems that interpret and act on sensor inputs. Their data has a troublesome habit of arriving from the world rather than a tidy benchmark: lighting changes, cameras move, objects block one another, and different sensors may describe the same event in different formats. The work of sorting those records can determine which failures a model ever gets the chance to learn from.
The Handoff Problem
Voxel51’s launch announcement describes a path from raw multimodal recordings to searchable, curated training data, with support for active learning as models improve. In that approach, teams use a model’s performance to help choose what to review or label next. A system that struggles with certain scenes can direct attention toward more examples of those scenes rather than another batch of easy ones.
Consider a warehouse camera system trained to identify packages. If it performs well under bright overhead lights but misses packages in a dim aisle, a useful workflow would let a team find comparable recordings, review the failures, annotate relevant examples and evaluate the next model against that same class of scene. The warehouse is an illustration, not a reported Voxel51 deployment. The important detail is the loop: search determines which cases people see, annotation determines what a model learns, and evaluation determines whether anyone can tell if the change helped.
When those stages live in separate systems, an image might carry one identifier in storage, another in a labeling tool and a third in an evaluation report. Teams can manage those joins themselves, but someone must maintain them. Unification could save work by keeping a searchable record close to the decisions made about it. It could also make a single platform responsible for more of the team’s process. Convenience and dependence often arrive in the same box.
The strongest case for Voxel51 3.0 is therefore operational. Better organization can help engineers spend less time reconstructing which footage went into which experiment. It cannot, by itself, make a sensor capture an obscured object or make an annotation correct. If the examples selected for review leave out a recurring failure, a smoother pipeline can move that omission through the system faster.
Versioning Needs a Chain of Custody
Version 3.0 also adds dataset versioning and an agent with more than 45 tools, using the Model Context Protocol, or MCP, to connect the assistant with external tools and data. Dataset versioning addresses a basic question that becomes awkward once a team repeatedly edits its training set: what, precisely, did the model see?
Suppose one evaluation used a dataset before a batch of low-light recordings was added, while the next used it afterward. A recorded dataset version gives the team a way to identify that change. Without one, an apparent model improvement could reflect a different test set, a changed label or some other shift in the data. Versioning is a prerequisite for tracing those differences; it is not the whole audit trail. Reproducing an evaluation also requires the relevant labels, selection rules, model configuration and test procedure to remain identifiable.
For physical systems, the definition of a dataset can be unusually slippery. One recording might contain images, timestamps and readings from another sensor. If any of those pieces is corrected or falls out of alignment, the meaning of the example can change. A team assessing a versioning system would want to know whether it can reconstruct the collection and its annotations as they stood when an experiment ran, including changes made after reviewers spotted an error.
That is where a data platform becomes more than a filing cabinet. It influences which examples count as representative, which failures get named and which results remain comparable. The people doing annotation and review sit inside that process, even when a product description emphasizes automation. Someone still has to decide whether a strange sensor reading is a rare but valid case or a broken instrument.
An Agent at the Data Door
MCP gives Voxel51’s agent a standard way to connect an AI assistant to tools and data sources. The number of tools signals the breadth of actions the agent is intended to support, but the number alone says little about how those actions behave. For a team, an assistant that can find relevant recordings or organize routine queries could shorten the route from a model failure to the examples behind it.
Access creates the harder questions. A system that can search datasets may encounter sensitive recordings or information a team has restricted to certain workers. A system that can change curation or annotation state could affect later training and evaluation. Teams considering an agent in that position would need to establish which operations require approval, how permissions apply to its actions and what record remains of changes it makes. MCP supplies a connection mechanism; the rules governing a connected assistant have to work in the deployment.
Automation can also change who gets to inspect a decision. If an agent assembles a collection of apparent failures, reviewers need enough context to see why those examples were selected and what was excluded. Otherwise a convenient shortlist can become a quiet source of bias. The risk is familiar from older data pipelines, where selection rules shaped outcomes long before a model produced a prediction. Giving those rules a conversational interface does not remove their consequences.
Where the Workflow Meets the Hardware
Voxel51 3.0 has a coherent target: the recurring labor of finding, labeling and comparing data from systems that operate in messy environments. Its announced features do not, on their own, show how well the platform handles variation across devices and formats, whether evaluations stay reproducible as datasets change, or how an agent’s permissions are enforced. Those are the tests a team would have to run against its own recordings and procedures.
The incentives are clear enough. Developers stand to gain a shorter route from a failure to a revised dataset. Voxel51 stands to become a central workspace for that route. Annotators, reviewers and people captured by sensors have interests that a faster workflow does not automatically protect: accurate labels, accountable changes and limits on access to recordings. A platform can make those concerns easier to manage if its controls hold up under everyday use; centralizing data can also raise the cost of getting them wrong.
The next revealing result will be less glamorous than a robot demonstration. It will be whether a team can identify a failure in one sensor record, trace the decision to include it, and reproduce the evaluation that followed without having to guess which version of the data was on the desk.
More Like This
Why Your MCP Server Won't Survive Production
Most MCP servers collapse under real workloads. Lenses engineers explain the security cliff between local dev and production—and how to cross it.
What REA Can See When an AI Agent Reverse-Engineers Apps
REA links AI agents to app-inspection tools, but a convincing reconstruction still depends on what the tools observed, what stayed hidden and what was tested.
AI Models vs Agentic Harnesses: What Drives Performance
The AI model isn't what makes an AI system powerful—it's the infrastructure wrapped around it. Here's what the model vs. harness distinction actually means.
Connecting MCP Servers to Claude: What It Means
MCP servers let Claude reach beyond the chat window into files, databases, and live systems. Here's what that connectivity actually looks like—and why it matters.
Six Protocols That Make AI Agents Actually Work
Google's agent protocol stack—MCP, A2A, UCP, AP2, A2UI, AGUI—explained through a kitchen manager demo. What each protocol does and when to reach for it.
Nvidia Cosmos 3 Puts Physical AI Through Virtual Trials
Nvidia's Cosmos 3 links language, video and robot action, but its near-term value may lie in ranking policies before costly real-world robot safety tests.
EU AI Act: How to Tell If Your AI Is High-Risk
The EU AI Act's high-risk classification isn't just about what your AI does—it's about how it's deployed. Here's what organizations need to understand now.
AI Coding Tools and the Developer Skills Trade-Off
New research shows AI coding tools may improve productivity while quietly eroding developer skills. What does the data actually say—and who should be worried?