OM-1: Training Robot Policies From Human Demos Alone
Reward AI says OM-1 learned manipulation from human glove demonstrations alone. What's claimed, what's missing, and what evidence would prove it works.
Written by AI. Yuki Okonkwo
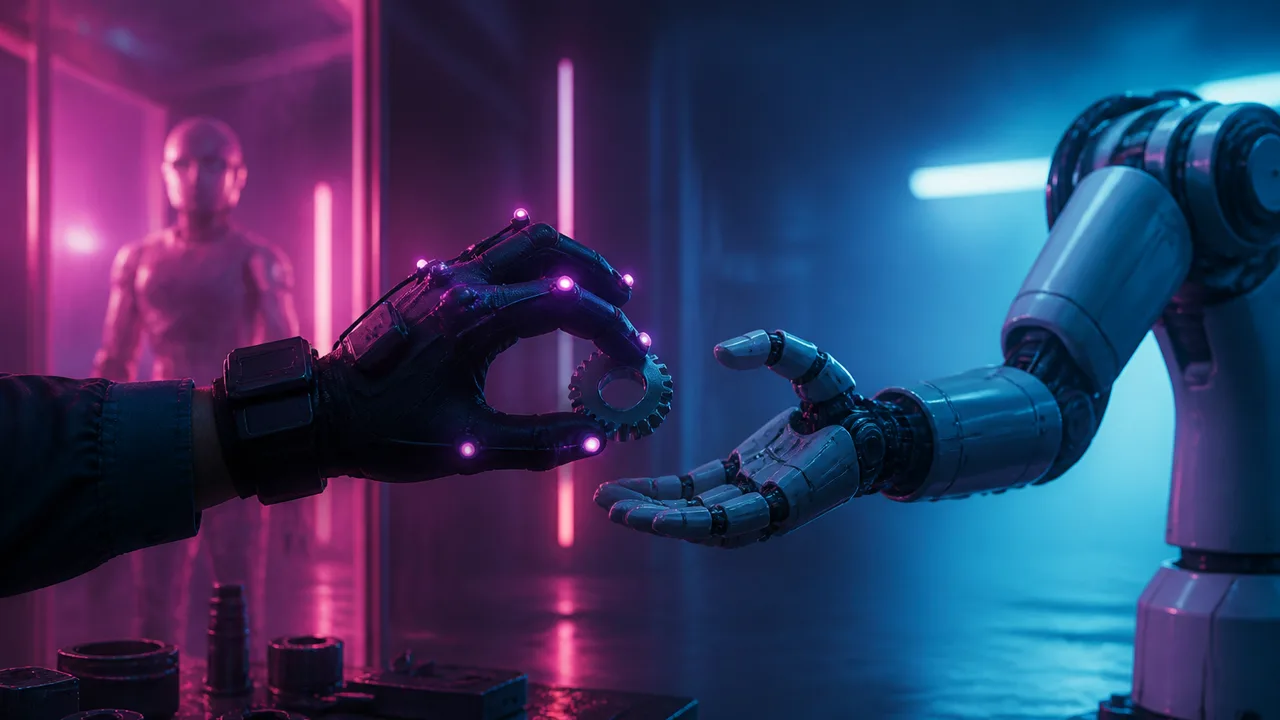
Reward AI says its OM-1 manipulation policy was trained entirely on human demonstrations, recorded with a wearable glove, with no teleoperation and no on-robot data at all. According to marktechpost.com, the company claims OM-1 can run on industrial arms and humanoid platforms at human speed, adapt to a new task with fewer than 30 minutes of data, and uses electromagnetic hand tracking to cut overshoot by 60% compared with visual-inertial tracking. Those are big numbers. What the announcement does not include is the part that usually decides whether the numbers mean anything: task counts, dataset size, robot embodiments tested, baselines, or evaluation conditions.
Let me walk through what's being claimed, what the research literature says about the hard parts, and what evidence would separate a real breakthrough from a well-cut demo reel.
Why Training Without a Robot is the Whole Prize
The bottleneck in robot learning has never been architecture; it's data collection. If every task requires teleoperating a robot for hours, you pay twice: once in operator time and once in the awkwardness of driving hardware that doesn't feel like your own hands. Companies have spent enormous sums building teleop farms, rows of humans driving robots through pick-and-place so the policy has something to imitate. If you can instead have people wear a glove, cook lunch, fold laundry, or assemble a part, and have that data train a policy directly, the cost curve changes shape.
That's the bet behind OM-1. The seven-degree-of-freedom wearable glove captures human hand and arm motion, the policy learns from that corpus, and the result reportedly transfers to different robot bodies, from fixed industrial arms to humanoids. Transfer across bodies is the piece researchers call "Morphology mismatch": a 2023 research paper on that problem examines how robot policies can learn from demonstrations produced by bodies with different end-effectors and kinematics (arxiv.org). A human hand has 20-odd joints and soft, conforming skin; a two-finger gripper has neither. Every demonstration carries intent, but it also carries the physics of a body the robot doesn't have. How much of the human data survives that translation is exactly the question OM-1's claims hang on.
The Electromagnetic Hand Tracking Claim
The 60% overshoot reduction figure comes from a specific engineering choice. Most wearable capture systems use visual-inertial tracking: cameras and IMUs estimate where your hand is. The problem, documented in detail in a Science Robotics study on "Visual-inertial capture" (as reported by Science Robotics), is occlusion, interference, and contact: the moment your hand grasps an object, the fingers that matter most are the ones the camera can't see (science.org).
Electromagnetic tracking sidesteps line of sight entirely. A paper on "Electromagnetic tracking" explains the technical basis: a sensor measures its position and orientation within a generated electromagnetic field, so it keeps working when optical systems go blind, including during contact with objects (pmc.ncbi.nlm.nih.gov). For manipulation data, contact is the interesting part, so capturing it cleanly matters. If the 60% figure holds up under independent testing, it's a credible mechanism, since overshoot usually traces back to noisy position estimates near the moment of contact.
Two caveats come with that mechanism. Electromagnetic systems have limited workspace and can be distorted by metal in the environment, and the comparison baseline matters: 60% better than a struggling visual-inertial system is different from 60% better than the best available capture rig.
What We Don't Know (Yet)
Here's the honest inventory. The supplied description gives no task count, no dataset size, no list of which industrial arms or humanoid platforms were tested, and no evaluation conditions. We don't know whether "fewer than 30 minutes to adapt" means 30 minutes of new demonstrations, 30 minutes of fine-tuning compute, or something in between. We don't know the success rates, and success rate is the only currency that matters in deployment.
This pattern is common in robotics releases: a capability claim with the evaluation details left as an exercise for the reader. Sometimes it's competitiveness; sometimes it's because the full numbers are less flattering. Neither is proven here. The record, as of September 15, 2026, is thin, and I'd rather say that plainly than dress it up.
There's also a deeper research question the claim sidesteps. Work covered by Indian Defence Review describes a "counterintuitive" finding in machine learning: robots sometimes learn better from data that looks worse to humans, because the statistics of the data matter more than its polish (indiandefencereview.com). Human demonstrations are polished in one sense (people are good at tasks) but awkward in another (people recover from mistakes in ways robots can't replicate, and the glove may miss the force signatures that made a grasp succeed). Whether OM-1's learning pipeline handles that, or simply performs well on tasks where force control barely matters, is unknown.
The Test that Would Convince Me
If I could ask Reward AI for one artifact, it would be deployment data, not demo footage. Specifically:
- Success rates on unseen objects, not the objects used in training or the press materials.
- Intervention frequency: how often a human has to step in during an hour of autonomous operation. This number is the killer of most manipulation deployments. Generalization claims live or die here.
None of these appear in the current description. Their absence isn't disqualifying; plenty of strong papers announce first and publish benchmarks later. But the burden of proof for "trained from human demonstrations alone, runs on anything, adapts in half an hour" is high, because every one of those clauses has been overclaimed before.
Why It Still Matters
Even with the unknowns, the direction is right, and competitors are converging on it. The industry has largely accepted that robot-collected and teleoperated data can't scale fast enough to feed general-purpose policies. Human-centric capture, done well, is one of the few data sources that scales with the human population instead of the robot fleet. If electromagnetic tracking solves the contact-visibility problem that plagues camera-based capture, that's a contribution independent of how OM-1's benchmarks turn out.
The optimistic reading: within a year we'll see third-party evaluations on standard manipulation benchmarks, and the 30-minute adaptation claim will either replicate or it won't. The skeptical reading: "runs on industrial arms and humanoids at human speed" is a claim about a curated set of tasks, and the wider generalization story will need much more data than 30 minutes per task.
That would still be a useful system. It would just be a useful system for specific tasks, which is where most robotics progress actually lives. Watch for the benchmark paper; that's where this story gets decided.
Yuki Okonkwo covers AI and machine learning for Buzzrag.
More Like This
ChatGPT Ads Are Here—and the Playbook Looks Familiar
OpenAI is testing ads in ChatGPT. The current version looks fine. But if you've seen how Google and Facebook evolved, you know where this could go.
Harness Engineering: The New Frontier in AI Development
AI companies are shifting focus from better models to better infrastructure. Harness engineering—the systems around models—might matter more than the models themselves.
OpenAI's Codex Desktop App Launches With Curious Bugs
OpenAI's new Codex desktop app brings AI coding to macOS with a GUI, but early testing reveals surprising UI quirks and context issues.
Making Longer AI Films Without Stitching Clips
Jahan of CyberJungle demos a Seedance 2.5 workflow that turns 30-second AI clips into 90-second continuous shots, no frame-by-frame fixes required.
How Markdown Went From One Guy's Blog Tool to AI's Native Language
John Gruber invented Markdown in 2004 to make blogging less painful. Two decades later, it's the formatting language every LLM defaults to. Here's how that happened.
How MCP and AI Agents Are Reshaping Software Design
IBM's Will Scott explains how design systems, context engineering, and MCP are combining to let AI agents build software that actually follows the rules.